Monarch Attention

The attention module in transformer architectures is often the most computation and memory intensive unit. Many researchers have tried different ways to approximate softmax attention in a compute efficient way. We have a new approach that uses the Monarch matrix structure along with variational softmax to quickly and accurately approximate softmax attention in a zero-shot setting. The results are very exciting — we can significantly decrease the compute and memory requirements while taking at most a small hit to performance. This figure shows the performance versus computation of our “Monarch-Attention” method as compared to Flash Attention 2 (listed as “softmax”) and other fast approximations.
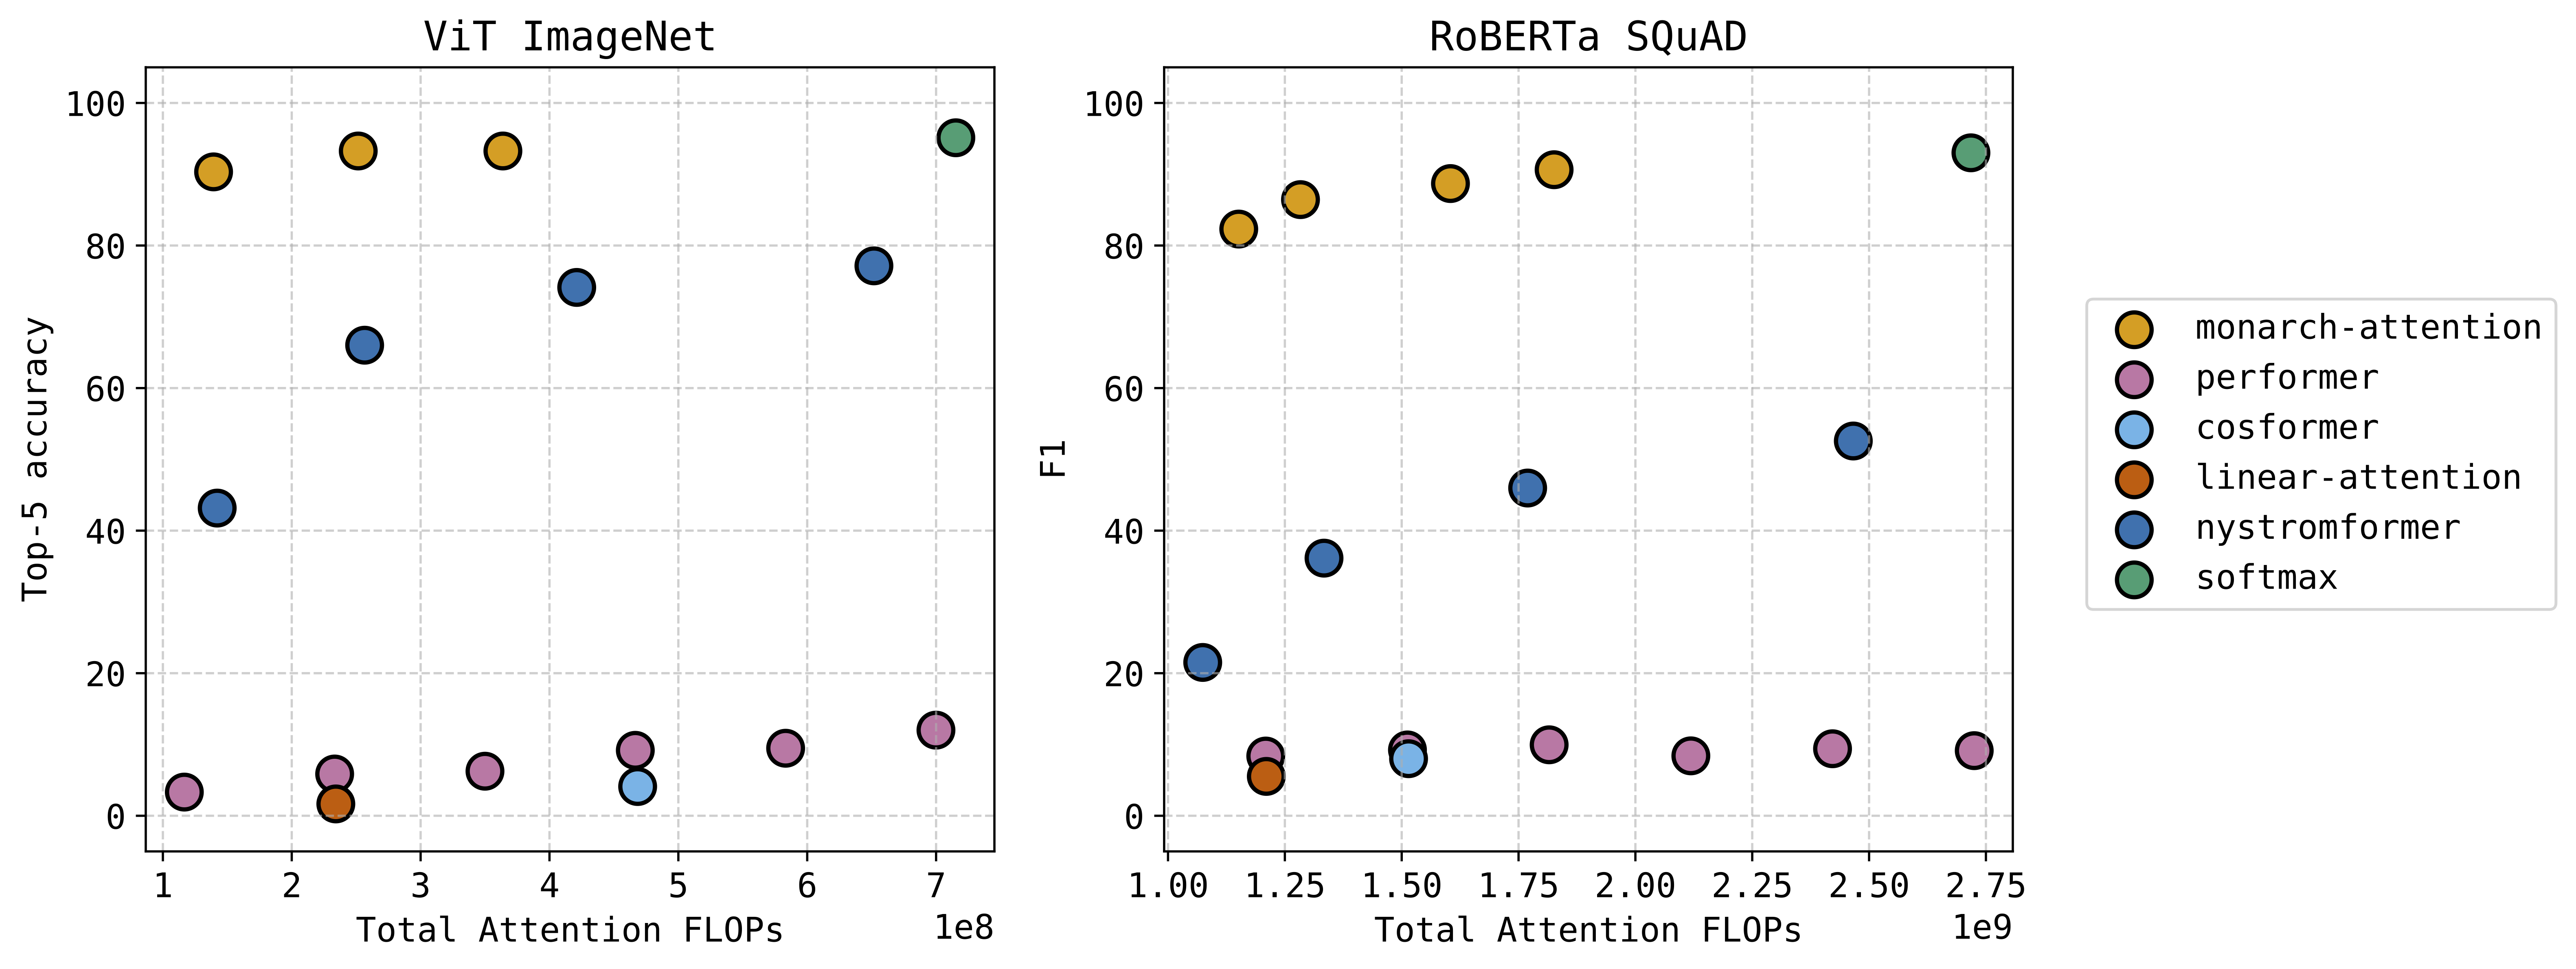
See the paper for additional results, including hardware benchmarking against Flash Attention 2 on several sequence lengths.

Can Yaras, Alec S. Xu, Pierre Abillama, Changwoo Lee, Laura Balzano. “MonarchAttention: Zero-Shot Conversion to Fast, Hardware-Aware Structured Attention.”
https://arxiv.org/abs/2505.18698
Code can be found here.

SDP Relaxation paper in SIMAX

I’m excited that our paper “A Semidefinite Relaxation for Sums of Heterogeneous Quadratic Forms on the Stiefel Manifold” has been published in the SIAM Journal on Matrix Analysis and Applications. https://doi.org/10.1137/23M1545136. We were inspired to work on this problem after it popped up inside the heteroscedastic PCA problem. It’s a fascinating, simple, general problem with connections to PCA, joint diagonalization, and low-rank semidefinite programs. Applying the standard Schur relaxation to this problem gives a trivial (and incorrect) solution, but one minor change makes the relaxation powerful and even tight in many instances. You can find the code for experiments here.

Code for Deep LoRA

Our ICML paper “Compressible Dynamics in Deep Overparameterized Low-Rank Learning & Adaptation” shows that it is possible to get the benefits of deep overparameterization without increasing the number of trainable parameters. The code for our experiments can be found at Can’s github site: https://github.com/cjyaras/deep-lora-transformers. We welcome any thoughts and questions if you use and adapt our code for your problem!

Code for Subspace Tracking with Missing Data

Code for my Proceedings of IEEE paper with Yuejie Chi and Yue Lu, Streaming PCA and Subspace Tracking: the Missing Data Case can be found here.

Optimally Weighted Heteroscedastic PCA Code

We have updated our paper on optimally weighted heteroscedastic PCA and here is the code to run the experiments. In this work we show how to weight data before solving PCA, under a spiked covariance model with heteroscedastic additive noise. Surprisingly, the weights are not inverse noise variance, and neither are they 0/1 discarding the noisiest points, but instead the optimal weights are in between these two standard heuristics.

HePPCAT in TSP

Our work on heteroscedastic PCA continues with our article “HePPCAT: Probabilistic PCA for Data with Heteroscedastic Noise,” published in IEEE Transactions on Signal Processing. In this paper we developed novel ascent algorithms to maximize the heteroscedastic PCA likelihood, simultaneously estimating the principal components and the heteroscedastic noise variances. We show a compelling application to air quality data, where it is common to have data both from sensors that are high-quality EPA instruments and others that are consumer grade. Code for the paper experiments is available at https://gitlab.com/heppcat-group, and the HePPCAT method is available as a registered Julia package. Congratulations to my student Kyle Gilman, former student David Hong, and colleague Jeff Fessler.

Online matrix factorization for Markovian data

Hanbaek Lyu, Deanna Needell, and I recently had a manuscript published at JMLR: “Online matrix factorization for Markovian data and applications to Network Dictionary Learning.” In this work we show that the well-known OMF algorithm for i.i.d. stream of data converges almost surely to the set of critical points of the expected loss function, even when the data stream is dependent but Markovian. It would be of great interest to show that this algorithm further converges to global minimizers, as has been recently proven for many batch-processing algorithms. We are excited about this important step, generalizing the theory for the more practical case where the data aren’t i.i.d. Han’s work applying this to network sampling is super cool — and in fact it’s impossible to sample a sparse network in an i.i.d. way, so this extension is critical for this application. The code is available here. Han is on the academic job market this year.

Online Tensor Completion and Tracking

Kyle Gilman and I have a preprint out describing a new algorithm for online tensor completion and tracking. We derive and demonstrate an algorithm that operates on streaming tensor data, such as hyperspectral video collected over time, or chemo-sensing experiments in space and time. Kyle presented his work at the first fully virtual ICASSP, which you can view here. Anyone can register for free to this year’s virtual ICASSP and watch the videos, post questions, and join the discussion. Kyle’s code is also available here.

Improving K-Subspaces via Coherence Pursuit

John Lipor, Andrew Gitlin, Bioashuai Tao, and I have a new paper, “Improving K-Subspaces via Coherence Pursuit,” to be published in the Journal of Special Topics in Signal Processing issue “Robust Subspace Learning and Tracking: Theory, Algorithms, and Applications.” In it we present a new subspace clustering algorithm, Coherence Pursuit – K-Subspaces (CoP-KSS). Here is the code for CoP-KSS and for our figures. Our paper considers specifically the PCA step in K-Subspaces, where a best-fit subspace estimate is determined from a (possibly incorrect) clustering. When a given cluster has points from multiple low-rank subspaces, PCA is not a robust approach. We replace that step with Coherence Pursuit, a new algorithm for Robust PCA. We prove that Coherence Pursuit indeed can recover the “majority” subspace when data from other low-rank subspaces is contaminating the cluster. In this paper we also prove — to the best of our knowledge, for the first time — that the K-Subspaces problem is NP-hard, and indeed even NP-hard to approximate within any finite factor for large enough subspace rank. 

Group OWL Regularization for Deep Nets

My student Dejiao Zhang’s code for our paper Learning to Share: Simultaneous Parameter Tying and Sparsification in Deep Nets can be found at this link. We demonstrated that regularizing the weights in a deep network using the Group OWL norm allows for simultaneous enforcement of sparsity (meaning unimportant weights are eliminated) and parameter tying (meaning co-adapted or highly correlated weights are tied together). This is an exciting technique for learning compressed deep net architectures from data.